Evidano home
gLOCAL Evaluation Week 2026 event reportResponsible AIMagic Bus India Foundation

When Qualitative Evaluation Meets AI: A Human-Checked Workflow for Adolescent Life Skills

Evidano7 min read
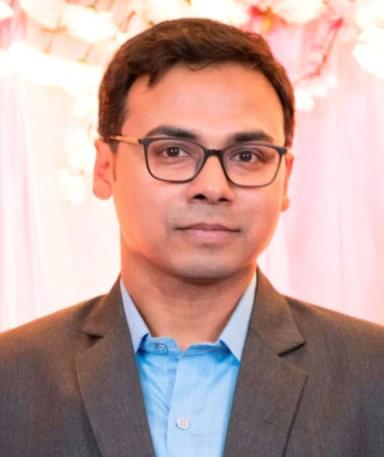
Somenath Ghosh, Deputy General Manager, Impact at Magic Bus India Foundation

Featured researcher: this report is featured independently and does not evaluate Evidano.

When a qualitative evaluation spans interviews in several languages, the bottleneck rarely sits in one place. Audio has to become text, regional-language transcripts may need translation, and researchers then have to code, compare, synthesize, check interpretations against field notes, and turn the result into something programme teams can use. AI can accelerate several of those steps, but speed creates a second problem: how do evaluators know that nuance has not been lost on the way?

That tension sits at the centre of a 2026 gLOCAL Evaluation Week session from Magic Bus India Foundation, “Exploring AI-enhanced Efficiency in Qualitative Assessment of Adolescent Life skills.” The session describes a hybrid workflow for evaluating life-skills programmes among adolescents, combining quantitative measurement, recurring qualitative field assessment, and AI-assisted processing. Its most useful contribution is not a claim that AI can replace qualitative analysis. It is a practical account of where automation can enter the workflow and where human verification remains necessary.

We spoke with Somenath Ghosh, Deputy General Manager, Impact (Monitoring and Evaluation) at Magic Bus India Foundation, to learn more about how the team is combining AI-assisted analysis with human checking in multilingual life-skills evaluation.

About the report

Research question

How can qualitative assessment help evaluators understand changes in adolescents’ life skills that quantitative scores alone may not explain, and how can AI support that process without displacing researcher judgement? The session follows the workflow from interviews and observations through transcription, translation, coding, synthesis, and reporting.

Key finding

The report presents a human-AI model rather than an automated one. AI is used to speed transcription, translation, preliminary thematic analysis, synthesis, and visualization, while researchers verify transcripts and translations, triangulate across respondent groups and quantitative findings, and review AI-generated outputs before reporting.

Why this research matters

Life skills are difficult to reduce to a single score. Confidence, self-efficacy, decision-making, communication, resilience, and changing gender attitudes can appear differently at home, in classrooms, and in the way adolescents describe their own choices. Magic Bus therefore pairs quantitative assessment with Quarterly Field Assessments designed to capture how change is experienced and observed.

That combination matters because the hardest part of qualitative work is often not collecting a rich interview. It is processing many interviews consistently and quickly enough for findings to inform decisions while the programme is still running. The report describes work across 22 Indian states, so the pressure to turn qualitative material into usable evidence is substantial.

The case also offers a useful counterweight to simplistic debates about AI in qualitative research. The workflow assumes that automation can help with labour-intensive tasks, but it names the places where it can fail: cultural nuance, language-specific transcription and translation, prompt dependence, and interpretation of implicit meaning. Somenath Ghosh reflected on the practical stakes: “The cultural nuances, local expressions, sarcasm, hesitation or sensitive issues are often embedded in multilingual conversations. Only involving AI may miss those parts in transcriptions. So, human judgement is also essential for understanding the context, identifying potential biases, and validating findings about how evidence should be interpreted and used.”

Key findings from the report

The report is best read as a methodological case study rather than as an impact evaluation with a single treatment effect or headline outcome. Three contributions stand out.

  • Life-skills measurement is deliberately mixed-method. Magic Bus organizes its framework around emotional, cognitive, and social domains, with 11 core life skills and roughly 40 competencies. Its Situational Judgment Test was refined from an initial 50 items to 24 vignette-based scenarios, while qualitative assessments gather perspectives from adolescents, parents, teachers, life-skills educators, and structured observation. The design gives evaluators different kinds of evidence about the same programme rather than asking one instrument to do everything.
  • AI is inserted into a defined workflow, not given end-to-end control. Field teams collect recordings and notes; ElevenLabs generates draft transcripts; regional teams correct them; AI translates regional-language material into English; researchers validate translations; ChatGPT supports inductive thematic analysis; findings are integrated with quantitative and programme data; Claude supports narrative synthesis; Napkin AI supports visual summaries; and Canva is used for final presentation. Human checks are placed before and after several automated stages rather than only at the end.
  • Quality assurance is treated as part of the method. Safeguards include transcript verification, translation validation, sequential probing, cross-checking against quantitative findings, comparisons across assessment rounds, triangulation across respondent groups, case-study validation, and expert review of AI-generated outputs. The report also states that AI may miss cultural nuance, produce uneven transcription or translation across languages, and generate outputs that depend heavily on prompt quality. Those cautions define the limits within which the claimed efficiency gains should be interpreted.

Taken together, the case suggests that the real design question is not whether to use AI, but where to place it and what should be checked before an output is trusted. Ghosh reflected on the workflow: “The aspects that requires the greatest level of both assistance from AI and manual attention is the interpretation and validation of findings. While human review remains essential to ensure translation and transcription are done accurately, the manual attention is also greatly needed to assess the quality of AI-generated codes, address potential biases during interpretation and ensure that sensitive perspectives are understood and represented correctly.”

Methods and research approach

The session describes a mixed evaluation system built around structured measurement and qualitative inquiry. On the quantitative side, Magic Bus uses a Situational Judgment Test, in which adolescents respond to realistic scenarios requiring judgement or decision-making. On the qualitative side, Quarterly Field Assessments use interviews with adolescents, parents, teachers, and life-skills educators, alongside observation checklists, field notes, audio recordings, and structured facilitation protocols.

The qualitative component is designed for triangulation. Adolescents can describe their aspirations, confidence, communication, and behavioural changes; parents can report family relationships and decision-making; teachers can observe classroom participation and leadership; educators can comment on implementation; and field observations provide another record of participation and facilitation quality. A claim about change can therefore be examined from several vantage points.

AI enters after data collection, but the report does not present a benchmark study of AI accuracy against human coding. It also does not report the field sample size for the qualitative assessments or a quantified before-and-after measure of time saved. Its claims about efficiency and consistency should therefore be read as practice-based observations from the workflow, not as independently validated performance estimates.

Broader implications

For evaluation teams, the strongest lesson is procedural. Responsible AI use depends less on choosing a single “best” model than on designing checks around each task. Transcription should be corrected against audio and field notes. Translation should be reviewed for local meaning. Themes should be challenged against raw data and across respondent groups. Narrative synthesis should not become a shortcut around interpretation.

The report also points to a shift in evaluator skills. If AI takes on more mechanical processing, evaluators may spend relatively more time on prompt design, quality assurance, triangulation, interpretation, and deciding whether an apparent pattern is meaningful. That requires researchers to stay close enough to the data to recognize when a fluent output is contextually wrong.

For organizations collecting qualitative data at scale, the case offers a practical template worth testing, while leaving important questions open. How consistent are themes across languages and tools? How often do researchers overturn AI-generated codes or summaries? What kinds of error survive human review? Ghosh reflected on what teams should consider before scaling such an approach: “First an evaluation team needs clear quality assurance protocols to validate AI-generated transcriptions, translations, coding and thematic analysis. Second, a strong ethical and data protection measures include secure data storage, informed consent procedures, confidentiality safeguards, and clear guidelines on how AI tools process sensitive information. Last but not the least, evaluators need sufficient capacity and training to understand both the strength and limitations of AI in the process of qualitative assessment.”

About Somenath Ghosh

Somenath Ghosh, Deputy General Manager, Impact at Magic Bus India Foundation

Somenath Ghosh is Deputy General Manager, Impact at Magic Bus India Foundation. He has more than a decade of experience across monitoring, evaluation, research, data systems, and AI-enabled analytics. He holds a PhD in Economics from Visva-Bharati, completed in 2025, and has worked on mixed-method evaluations, MEL frameworks, and technology-enabled evidence systems. Earlier roles included Lutheran World Services India, MANT, and the Agro-Economic Research Centre at Visva-Bharati. Besides, he has published several scholarly articles in reputed Scopus‑ and Web of Science–indexed journals, including International Critical Thought (Routledge) and Social Science and Humanities Open (Elsevier).

About the authors

  • Dr. Somenath Ghosh (Deputy General Manager Impact, Magic Bus India Foundation, India)
  • Sukanya Bose (Assistant Manager Impact, Magic Bus India Foundation, India)
  • Dr. Ajay K Singh (Head of Impact, Magic Bus India Foundation, India)

Read the article

Read the full event report, presented at gLOCAL Evaluation Week 2026, “Exploring AI-enhanced Efficiency in Qualitative Assessment of Adolescent Life skills,” published on the gLOCAL Evaluation Week website in 2026.

Full citation

Magic Bus India Foundation. (2026). Exploring AI-enhanced efficiency in qualitative assessment of adolescent life skills [Event report]. gLOCAL Evaluation Week 2026. www.glocalevalweek.org/sites/default/files/2026-06/Glocal%20proceedings%20note.pdf

View the publication

We are grateful to Dr. Ghosh for sharing his perspective on this work and for his contribution to the responsible, transparent use of AI in qualitative evaluation.

Research, accuracy and responsible AI

How Evidano's output has been evaluated, how its models were built, how your data is handled, and how to disclose or cite AI use in your own work.

  • Resource

    Human vs AI: validated accuracy benchmarks

    Four head-to-head comparisons against expert human analysis — 371 interview transcripts with Arizona State and Penn State, 298 evaluation reports, 224 open-ended survey responses with UT Austin and Wichita State, and a 160-response manual-coding review.

  • Resource

    How Evidano’s models were trained

    Model provenance for research-ethics review: a provenance-tiered curated corpus, and customer uploads, prompts and outputs excluded from training entirely.

  • Resource

    Data security for qualitative research

    Encryption in transit and at rest, customer-controlled deletion, regional storage, and SOC 2 Type 2, GDPR, HIPAA-ready and CCPA/CPRA compliance.

  • Resource

    How to cite and disclose Evidano

    Citation formats in APA, MLA, Chicago, Harvard and Vancouver, methods-section wording per workflow, and an AI-policy review of 41 journals across 8 disciplines.