Evidano home
Published in Discover EducationResponsible AICalifornia State University, Sacramento

With Unrestricted AI, Students’ Methods Sections Converged, but Their Use of Evidence and Theory Did Not

Evidano9 min read
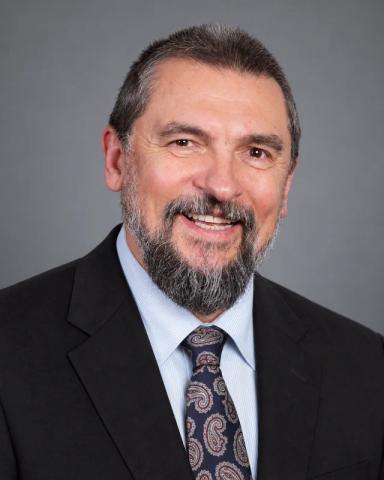
Alexander M. Sidorkin, Professor of Education at California State University, Sacramento

Featured researcher: this paper is featured independently and does not evaluate Evidano.

Imagine an undergraduate qualitative methods course in which every student is expected to use generative AI, without limits, to write a full qualitative research manuscript and submit it to a peer-reviewed journal. Most of the students enter without prior coursework in qualitative research or sustained experience writing extended scholarly manuscripts. For many instructors, the immediate worry is that AI will make every manuscript look the same, leaving nothing meaningful to assess. The opposite worry is that the task is simply too ambitious for novices. Both worries turn on the same question: when AI is part of the working environment, which parts of qualitative research work does it carry, and which still depend on the researcher?

That question is at the heart of “Authentic assessment in an AI-integrated qualitative research methods course,” published in Discover Education in 2026 by Alexander M. Sidorkin of California State University, Sacramento. The single-semester case study examines a Fall 2025 undergraduate qualitative methods course in child and adolescent development, where students used a course-specific AI Class Companion and other AI tools throughout the development of their manuscripts. It combines an analysis of variation across 33 final manuscripts with a qualitative comparison of four contrasting students’ AI conversation logs.

We spoke with Alexander M. Sidorkin of California State University, Sacramento, to learn more about how the course was designed, what the manuscripts revealed, and what it means to teach qualitative research when AI is part of the toolkit.

About the article

Research question

When students have unrestricted access to generative AI while producing an authentic qualitative research manuscript, does AI compress their work into a uniform quality band, or do meaningful differences remain on the dimensions that authentic assessment needs to capture? And what process differences distinguish students with stronger and weaker outcomes?

Key finding

AI access did not eliminate meaningful variation. Methods specification clustered strongly near the top of its scale, but two indicators of judgement, how closely interpretive claims were tied to evidence and how often interpretation drew on each student’s own theoretical framework, remained substantially dispersed. Stronger cases showed three recurring practices: criteria-based orchestration of the AI, supplying project-specific inputs the model could not infer, and substantive multi-turn iteration. The study frames these as candidate pathways rather than causal effects.

Why this research matters

Much of the debate about AI in higher education concerns academic integrity and detection. This study starts from a different premise: where generative AI has become part of professional knowledge work, excluding it may make assessment less like the real task rather than more. The design question then becomes which dimensions of performance remain attributable to the student’s own judgement when AI support is available. For qualitative research teaching, that is a pressing question, because the core skills, linking claims to data and interpreting findings through theory, are exactly the ones instructors most want to see.

The course offers a concrete test with a student population for which a journal-oriented manuscript is a substantial demand: juniors and seniors at a regional public, Hispanic-serving university with many first-generation students. By making AI use explicit, requiring AI conversation logs for selected assignments, and holding students responsible for the quality, veracity and originality of their work, the design makes the division of labour between student and AI visible. Alexander Sidorkin explained why he designed the course this way: “Qualitative researchers already work with these tools, and my students will too. Banning AI would have made the assessment less like the actual work of research. It also made something possible that I care about deeply: giving first-generation juniors and seniors a task once reserved for graduate students, writing a real manuscript and sending it to a real journal. The machine carries much of the procedural load, which frees the student, and me, to focus on the decisions only a researcher can make.”

Key findings from the article

Three findings stand out for anyone teaching or supervising qualitative research with AI.

  • Methods sections converged towards completeness. On a six-point Methods Specificity Index, the median manuscript scored the maximum of 6; 23 of 33 manuscripts (69.7%) received the top score and 32 of 33 (97.0%) scored 5 or 6, with one lower outlier. The author interprets this as consistent with effective structural scaffolding: the Class Companion could explain the expected elements, methodological vocabulary, ethical considerations and procedural structure of a methods section.
  • Evidence and theory remained diagnostic. Claim–Evidence Coupling ranged from 0.000 to 0.750 (median 0.333; interquartile range 0.273–0.542), and Theory–Interpretation Linkage ranged from 0.000 to 0.917 (median 0.444; interquartile range 0.250–0.500). Their interquartile ranges covered 26.9% and 25.0% of the possible scale, compared with 16.7% for methods specificity. Some manuscripts regularly grounded interpretation in quotations, observations or citations and in their own framework; others offered long stretches of interpretation without that grounding.
  • How students directed AI mattered. Comparing two stronger and two weaker cases, selected by total course points, the analysis identified three candidate pathways. Stronger students used the Companion for repeated criteria checks, asking what was missing or misaligned; they supplied inputs the tool could not infer, such as data-source details, sampling decisions and what themes meant; and they iterated substantively, requesting alternatives and rejecting versions. Weaker cases relied more on first-pass outputs.

Taken together, the findings suggest a division of cognitive labour in which AI scaffolds procedural demands more readily than it resolves situated interpretive judgement. As the paper puts it, access to the technology was insufficient to produce equivalent outcomes. Alexander Sidorkin reflected on what the manuscripts showed: “I expected the methods sections to look alike, and they did. What surprised me was how clearly the differences survived everywhere else. Two students could ask the same tool for help and end up with very different papers, because one kept bringing the conversation back to her own data while the other accepted whatever came first. AI produces fluent text with ease, but it has no idea what a student’s interviews actually said.”

Methods and research approach

The course met twice weekly across a 16-week semester and was organised around a single project: a qualitative research manuscript of at least 5,000 words, built up through cumulative assignments (introduction, theoretical framework, methods, findings and discussion) and submitted to a journal as part of the final assignment. Sessions followed a studio format, with students working on their own projects in small groups. Students used the course’s required Class Companion, a custom GPT configured to support learning “without providing completed assignments,” and were also free to use ChatGPT and other AI platforms. Grading used a five-criterion rubric covering originality, theoretical framework, method selection and execution, data use and analysis, and academic writing conventions. Thirty-six students enrolled and 33 consenting students’ final manuscripts were analysed under a Sacramento State IRB protocol.

Dispersion was estimated with three rubric-proximal heuristic indicators specified in advance: the Methods Specificity Index (one point for each of six method components) and two proportions computed over interpretive statements, identified by fixed inference markers and checked within a three-sentence window for evidentiary or theoretical support. Application of the rules was assisted by ChatGPT, manuscript by manuscript. Four cases were then examined through qualitative comparative analysis of AI conversation logs from two mid-semester assignments and revision tracing of later products, using the author’s Extended Executive Cognition framework as a sensitising lens.

The paper is transparent about its limits. It is a single-semester case study of one course with no comparison group, so AI orchestration cannot be separated from differences in preparation, effort or topic. The indicators are exploratory heuristics rather than validated instruments, and because their application relied on a generative model, classifications may vary across runs or model versions. The instructor, Companion designer, analyst and author of the interpretive framework are the same person, and the four cases were reviewed by a single analyst without independent coding.

Broader implications

For instructors, the paper proposes five design principles worth testing elsewhere: organise learning around a sustained authentic task; make at least part of the AI-supported process visible, for example through conversation logs; distinguish rubric dimensions by the kind of human contribution they require; treat AI orchestration as something to teach explicitly rather than assume; and shift attention from drafting towards reading, evaluating, integrating and revising AI-assisted text. Alexander Sidorkin was clear about where student and researcher judgement must stay in charge: “Wherever the work touches the data. AI can describe what a good theme looks like, but it cannot decide what a participant meant, which quotation carries the weight of a claim, or whether a theoretical lens actually fits the material. Those are acts of interpretation, and interpretation is where the researcher signs their name. I call the skill we need to teach discerning thinking: the ability to tell eloquent text from warranted text.”

The findings also speak to research practice more broadly. The practices that distinguished stronger students, checking work against explicit criteria, supplying the context a model cannot infer, and iterating rather than accepting first drafts, are the same habits that make AI-assisted qualitative analysis trustworthy in professional settings. Asked for his advice to educators and researchers adopting these tools, Alexander Sidorkin said: “Spend less energy detecting AI use and more energy teaching it. Ask students to show their conversations, not only their final drafts, and talk with them about how they steered the tool. Redesign rubrics so the points go to the parts of the work where human judgement still matters. And use the time AI frees up for what machines do poorly, which is sitting with a student and helping them think through their own project.”

It is equally important to be clear about what the study does not show. It does not establish that the course design caused the observed differences, that the pattern will transfer to other disciplines, institutions or student groups, or that the indicators measure research quality. What it shows is that, in this course, extensive AI access was compatible with meaningful variation in student performance, and that the dimensions requiring evidence integration and theoretical judgement remained the ones that told students apart.

About Alexander M. Sidorkin

Alexander M. Sidorkin, Professor of Education at California State University, Sacramento

Alexander M. (Sasha) Sidorkin is a Professor of Education at California State University, Sacramento, where he previously served as Dean of the College of Education and as the university’s Chief Artificial Intelligence Officer, and led its National Institute on Artificial Intelligence in Society. He is President of the Philosophy of Education Society. His work spans relational pedagogy, philosophy of education and the use of AI in university teaching and learning. His books include AI-Enhanced Pedagogies (Routledge, 2026), Embracing Chatbots in Higher Education (Routledge, 2024) and Pedagogy of Relation (Routledge, 2022).

About the authors

  • Alexander M. Sidorkin (California State University, Sacramento, CA, USA)

Read the article

Read the full research article, “Authentic assessment in an AI-integrated qualitative research methods course,” published in Discover Education in 2026.

Full citation

Sidorkin, A. M. (2026). Authentic assessment in an AI-integrated qualitative research methods course. Discover Education, 5, 1153. doi.org/10.1007/s44217-026-02273-4

View the publication

We are grateful to Professor Sidorkin for sharing his perspective on this study and for his contribution to the responsible, transparent use of AI in qualitative research.

Research, accuracy and responsible AI

How Evidano's output has been evaluated, how its models were built, how your data is handled, and how to disclose or cite AI use in your own work.

  • Resource

    Human vs AI: validated accuracy benchmarks

    Four head-to-head comparisons against expert human analysis — 371 interview transcripts with Arizona State and Penn State, 298 evaluation reports, 224 open-ended survey responses with UT Austin and Wichita State, and a 160-response manual-coding review.

  • Resource

    How Evidano’s models were trained

    Model provenance for research-ethics review: a provenance-tiered curated corpus, and customer uploads, prompts and outputs excluded from training entirely.

  • Resource

    Data security for qualitative research

    Encryption in transit and at rest, customer-controlled deletion, regional storage, and SOC 2 Type 2, GDPR, HIPAA-ready and CCPA/CPRA compliance.

  • Resource

    How to cite and disclose Evidano

    Citation formats in APA, MLA, Chicago, Harvard and Vancouver, methods-section wording per workflow, and an AI-policy review of 41 journals across 8 disciplines.