Evidano home
Published on AEA365Responsible AIKrueger Consulting

AI Can Code Faster. Evaluators Still Have to Decide What Matters

Evidano7 min read
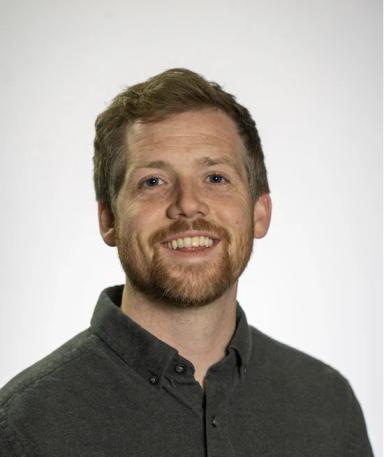
Brad Krueger, founder of Krueger Consulting

Featured researcher: this work is featured independently and does not evaluate Evidano.

Imagine an evaluator opening a set of interview transcripts after weeks of planning with program staff. An AI tool can scan the text in minutes and return a neat set of themes. The result looks efficient and plausible. But one outcome the team has been discussing for months is missing. The question is no longer whether the software can produce themes. It is whether the analysis still reflects what the program, participants, and evaluation are actually about.

That tension sits at the center of Brad Krueger’s 2025 AEA365 article, “Showing Up with Our Evaluation Competencies and Values in the Age of AI.” Krueger argues that AI makes familiar evaluation responsibilities more consequential: privacy, consent, equity, transparency, context, and professional judgment still have to shape how evidence is produced and used.

We spoke with Brad Krueger, founder and evaluation consultant at Krueger Consulting, to learn more about how evaluators can use AI without handing over the judgment that gives qualitative evidence its meaning.

About the article

Research question

How should evaluators approach AI when the technology can accelerate analysis but also introduces new questions about privacy, bias, consent, context, and accountability? Krueger’s answer is framed through the profession’s existing values and competencies rather than through a new technical framework.

Key finding

AI can make parts of qualitative analysis much faster, but useful adoption depends on evaluators choosing tools deliberately and correcting their outputs with contextual knowledge. The article’s clearest example is a live project in which an AI coding workflow saved time yet missed an important theme that the evaluator recognized and restored.

Why this research matters

AI-assisted coding creates a deceptively simple choice: accept the machine’s organization of the data, or treat it as one provisional interpretation among several. Krueger’s article argues for the second. That distinction matters because evaluation is not only a technical exercise in sorting text. It is also a practice of deciding what evidence is relevant, whose perspective is represented, what context changes the meaning of a statement, and how findings will be used.

The point is especially relevant to qualitative work, where a theme is not valuable merely because a model can detect repeated language. A theme becomes analytically meaningful when it captures something coherent and important in relation to the evaluation question and setting. Krueger reflected on the broader significance of this responsibility: “Our job is to decide what matters. AI can sort text and hand back themes in minutes, but it doesn’t know the program, the people, or why we’re asking the question in the first place. Evaluators bring that. If we step back and let the tool decide what counts as a finding, we’ve given away the part of the work that makes it evaluation.” His article suggests that the evaluator’s contribution is precisely the combination of method, ethics, and contextual knowledge that a generic tool does not automatically possess.

The point matters beyond evaluation. Research teams, nonprofits, and public agencies are being offered tools that promise faster interpretation of interviews and open-text data. Krueger’s example is a reminder that speed and plausibility are not substitutes for defensible analytic decisions.

Key findings from the article

The article is a practitioner reflection rather than a controlled tool benchmark, but three concrete contributions make its argument useful for researchers deciding how to incorporate AI into qualitative workflows.

  • Tool choice was treated as an evaluation decision, not a software purchase. On a live project, Krueger’s team compared a custom GPT in ChatGPT, CoLoop, and MAXQDA against their values and practical needs. They considered privacy and usability, then ran a small pilot before selecting the custom GPT. Krueger reports that the chosen workflow could complete work in “minutes not hours,” while using de-identified data in a paid account, returning cited evidence, and fitting the project’s consent process.
  • Human context changed the analysis. The AI-generated themes missed family reunification, an outcome that had been discussed extensively with program staff but was not explicit in the design documents supplied to the model. Krueger’s team recognized the omission because they knew the program context, then re-prompted the tool and refined the themes. The example shows a specific failure mode: a model can organize what is visible in its inputs while still missing what matters to people who understand the history and purpose of the work.
  • The article turns existing evaluator competencies into AI guardrails. Krueger links AI use to longstanding concerns about equity, rigor, transparency, utility, consent, bias, and responsible data practice. He argues that evaluators should help shape organizational AI policies and adoption decisions rather than leaving those choices entirely to vendors or technical teams. The contribution is less a new method than a professional stance: AI adoption should be governed by the same evaluative judgment used elsewhere in evidence work.

Taken together, these examples suggest that AI can be most useful when it creates a faster draft of the analytic work while leaving room for correction, challenge, and interpretation. Krueger reflected on the practical lesson from the pilot: “The missed theme stuck with me. Family reunification came up again and again in our conversations with program staff, but it wasn’t spelled out in the design documents we gave the tool, so the tool never saw it. Nothing in the output looked wrong. We only caught it because we knew the program. Now I treat the first set of themes as a draft, and I ask what’s missing before I ask what’s there.”

Methods and research approach

This AEA365 piece is not a formal empirical study with a stated sample or quantitative performance metrics. It is a practice-based reflection built around Krueger’s experience using AI in active evaluation work. Its most specific example is a qualitative coding project in which three tools were reviewed for alignment with project values and goals, including privacy and usability, followed by a small pilot.

The selected workflow used a custom GPT to assist with coding or theme development from de-identified qualitative data. Krueger emphasizes traceability through cited data and describes the process as substantially faster than manual work. Crucially, the evaluator did not treat the first model output as final: the team compared the generated themes with its fuller knowledge of program planning, detected the missing family-reunification theme, and refined the analysis through re-prompting.

Those details make the article useful as a methodological case example, but they also set its limits. Krueger does not report the number of interviews, exact prompt sequence, pilot composition, independent coding checks, or head-to-head accuracy measures. The “minutes not hours” comparison is therefore best read as one workflow experience, not a general estimate of time savings or proof that one product is more accurate than another.

Broader implications

For qualitative researchers, the article offers a practical definition of human oversight. It means deciding what data may be entered, what consent permits, what context the system needs, how themes should be challenged, and what omissions require correction. The evaluator remains responsible for the chain of reasoning from raw material to claim.

For organizations, Krueger makes a broader governance argument. Evaluators already work at the intersection of data quality, stakeholder interests, uncertainty, and use. Those competencies can help organizations ask better questions about AI adoption: Which tasks are appropriate to automate? What information should never be uploaded? How will outputs be checked? What happens when a model’s worldview or training data sits uneasily with the community being evaluated? These are operational questions, but also ethical and methodological ones.

The article does not establish a universal best practice for AI-assisted coding, and the tools themselves continue to change. Its more durable contribution is to insist that professional judgment should develop alongside the technology rather than after it. Looking ahead, Krueger reflected on the next practical step: “Before anyone opens a tool, agree as a team on what data can go in and what can’t. Check it against what participants consented to. For us that meant de-identified data in a paid account, and a tool that cites the evidence behind each theme so we can check its work. If you can’t answer the data question, you’re not ready to use AI on that project.”

About Brad Krueger

Brad Krueger, founder of Krueger Consulting

Brad Krueger, MPH, is the founder of Krueger Consulting, an equity-centered evaluation and consulting firm. He works with nonprofits, Tribal health organizations, health departments, and federally funded programs on program evaluation, data systems, grant support, and AI readiness. Brad trains evaluators and public health professionals to use AI responsibly, with a focus on privacy, consent, tool selection, and human review. He has led AI trainings for the American Public Health Association Conference, the Data Storytelling Collaborative, and the Public Health Club.

About the authors

  • Brad Krueger (Krueger Consulting, United States)

Read the article

Read the full article, “Showing Up with Our Evaluation Competencies and Values in the Age of AI,” published on AEA365 in 2025.

Full citation

Krueger, B. (2025, May 26). Showing up with our evaluation competencies and values in the age of AI [Integrating Technology in Evaluation TIG Week]. AEA365, American Evaluation Association. aea365.org/blog/integrating-technology-in-evaluation-tig-week-showing-up-with-our-evaluation-competencies-and-values-in-the-age-of-ai-by-brad-krueger/

View the publication

We are grateful to Brad Krueger for sharing his perspective on this article and for his contribution to the responsible, transparent use of AI in evaluation.

Research, accuracy and responsible AI

How Evidano's output has been evaluated, how its models were built, how your data is handled, and how to disclose or cite AI use in your own work.

  • Resource

    Human vs AI: validated accuracy benchmarks

    Four head-to-head comparisons against expert human analysis — 371 interview transcripts with Arizona State and Penn State, 298 evaluation reports, 224 open-ended survey responses with UT Austin and Wichita State, and a 160-response manual-coding review.

  • Resource

    How Evidano’s models were trained

    Model provenance for research-ethics review: a provenance-tiered curated corpus, and customer uploads, prompts and outputs excluded from training entirely.

  • Resource

    Data security for qualitative research

    Encryption in transit and at rest, customer-controlled deletion, regional storage, and SOC 2 Type 2, GDPR, HIPAA-ready and CCPA/CPRA compliance.

  • Resource

    How to cite and disclose Evidano

    Citation formats in APA, MLA, Chicago, Harvard and Vancouver, methods-section wording per workflow, and an AI-policy review of 41 journals across 8 disciplines.