Evidano home
Published in New Directions for Teaching and LearningResponsible AIBridgewater State University

When Generative AI Meets Human Thematic Analysis in Higher Education Assessment

Evidano8 min read
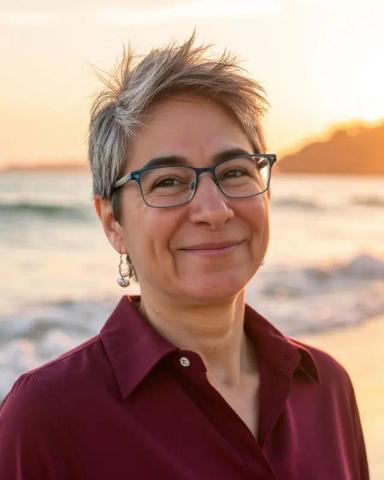
Ruth C. Slotnick, former Director of Assessment at Bridgewater State University

An assessment office can receive dozens of annual program reports in a single cycle. Some answers fit neatly into tables. Others arrive as open-ended reflections about curriculum, equity, student learning, or departmental practice. Those comments may contain the most useful clues for improvement, but they are also the slowest to interpret well, especially for a small team.

That tension sits at the center of Ruth C. Slotnick and Joanna Z. Boeing’s article, “Enhancing qualitative research in higher education assessment through generative AI integration: A path toward meaningful insights and a cautionary tale.” The study was an early exploration of generative AI in qualitative assessment, testing the free versions of Bard and ChatGPT-3.5 available in September 2023 against a human-led analysis. AI capabilities have advanced substantially since then, including the ability to process images and larger datasets and use connected tools. The study’s continuing contribution is its process for examining AI-assisted interpretations and retaining human responsibility for meaning-making.

The featured researcher is Ruth C. Slotnick, former Director of Assessment at Bridgewater State University, whose work spans institutional assessment, educational effectiveness, and the use of generative AI in assessment practice. Following her retirement in September 2026, she continues this work as a higher education and assessment consultant and Associate Editor of Research & Practice in Assessment.

About the article

Research question

How useful were the accessible generative AI tools available in 2023 for interpreting mixed qualitative and quantitative assessment data, and where did their outputs need human correction, contextualization, or restraint? The study also asked how assessment practitioners can integrate these tools without giving up the interpretive work that gives qualitative analysis its value.

Key finding

The early tools were fast and sometimes useful for theme generation, gap spotting, and producing additional perspectives, but their performance was uneven across formats and prompts. The authors’ central contribution is a practical human–AI workflow in which researchers establish the analysis, compare outputs, investigate discrepancies, supply missing context, and retain responsibility for interpretation.

Why this research matters

Institutional assessment provides a useful setting for examining AI-assisted qualitative research because the work is both practical and interpretive. Assessment professionals need to turn recurring data into decisions under time pressure, yet meaning may depend on program history, policy, accreditation expectations, or local initiatives. AI-assisted interpretation requires access to relevant context and people who can evaluate whether the resulting account fits the evidence.

Slotnick and Boeing make that distinction concrete. Their 2023 investigation shows why speed alone is not a sufficient measure of analytical quality. A response generated in seconds can still misread a chart, reverse a frequency judgment, flatten a thematic interpretation into a summary, or cite literature that is relevant but dated. Reflecting on the work, Slotnick offers this perspective: “AI can help us identify patterns and question our first interpretations. People remain the critical meaning-makers: we need to understand the context, examine what the evidence supports, and take responsibility for what happens next.” That distinction matters well beyond assessment offices, wherever rapid output risks being mistaken for trustworthy analysis.

Key findings from the article

Three findings show what the tools tested in 2023 could contribute and where the researchers needed to examine and correct their outputs.

  • Responses were fast, but reliability was uneven. In this study, the AI tools produced responses in roughly 3 to 15 seconds. Yet Bard struggled with the bar chart, initially identified only 5 of 13 response options, and made frequency errors. In the table analysis, Bard also incorrectly identified the least common practice after having reported it correctly in an earlier prompt, showing that fast output still required line-by-line checking.
  • Different tools produced different kinds of “insight.” For 30 open-ended responses totaling 1,619 words, Bard generated four broad themes after the text had to be converted to an image, while ChatGPT generated 13 themes with comments and a summary. When asked to analyze by college, Bard could not process the combined material and instead offered instructions, while ChatGPT produced what the researchers judged to be reasonable themes. Later, the authors noted that ChatGPT often produced more of a summary than a thematic analysis, an important distinction between describing content and interpreting patterns.
  • Prompting and context became part of the research method. The researchers repeatedly refined prompts, compared outputs with their own analysis, and supplied more explicit context when the systems misunderstood the data. The tools produced relevant references, recommendations, and some additional insights, but the literature was often outdated and the systems lacked knowledge of local campus initiatives and standards. The paper turns these observations into a 10-step guide that begins with reviewing platform capabilities and protecting confidentiality, then moves through testing, prompt refinement, cross-platform comparison, bias checking, dissemination, and reflection on equity implications. The guide draws on Jankowski and Slotnick’s (2015) five practitioner roles: assessment/method expert, narrator/translator, facilitator/guide, political navigator, and visionary/believer. These responsibilities remain relevant as the tools change.

The findings illustrate how AI-generated interpretations can give researchers additional material to examine. Errors, inconsistent responses, and unexpected insights all required a return to the evidence. Slotnick reflects: “I was struck by the additional insights the tools offered alongside their errors. That reinforced the value of questioning both the AI output and our own analysis. Human oversight requires more than checking whether the machine agrees with us.”

Methods and research approach

Over two weeks, the researchers used de-identified data from Bridgewater State University’s annual assessment system, covering 93 graduate and undergraduate programs across four colleges in 2022–2023. Faculty reports included a question asking programs to select from 13 response options about diversity, equity, and inclusion (DEI) practices and a follow-up open-ended question. The final dataset combined a bar chart, a frequency-and-percentage table, and 30 open-ended responses. These were faculty reports about program practices, not direct measures of student learning.

The researchers did not begin by asking AI to code the material. Each researcher first read and coded the data independently, kept reflective notes, and then reconciled coding decisions collaboratively using a modified ATLAS Looking at Data protocol. They used what the paper describes as “reflective thematic analysis” and constant-comparative analysis, moving between human-only findings and AI-assisted outputs. Bard and the free version of ChatGPT-3.5 were used for theming and related interpretation tasks. The free ChatGPT version could not process the chart image. The study did not test AI’s initial coding of the qualitative data.

That design gave the authors a human analysis against which to examine AI outputs, but it also defines the study’s limits. The sample was small and focused on one institution’s DEI assessment data. The work did not use statistical reliability or validity tests, the study period was brief, and only two free AI tools from 2023 were examined. The authors also note that de-identification reduced disclosure risks while removing context that could have improved interpretation. These limitations make the paper a careful methodological case study rather than a general benchmark of AI performance.

Broader implications

For researchers, the paper offers a practical way to think about AI assistance: not as a single step called “analysis,” but as a chain of decisions about data preparation, task delegation, prompting, verification, bias, and interpretation. That framing is especially useful for qualitative work, where a code is not the same as a theme, a summary is not the same as an interpretation, and frequency is not always a proxy for significance.

For institutions, the study argues that assessment professionals should have a voice in campus AI policy because they work across programs and routinely handle sensitive performance and perception data. The authors call for explicit protocols around transparency, confidentiality, accountability, and training. Their own 10-step guide makes those concerns operational, beginning with platform review and de-identification and ending with reflection on equity and social justice implications.

Newer models warrant fresh testing, but the process of comparing interpretations, supplying context, and examining consequences still holds. Slotnick’s subsequent RPA article with John Hathcoat and Will Miller, “The End of Assessment? Disruption and Transformation in the Age of AI,” extends these questions to the future of assessment practice. Looking ahead, she proposes: “I hope to see more qualitative dissertations in higher education assessment, including studies of AI-assisted inquiry, with findings and methods freely available for assessment practitioners to examine and use. I can imagine agentic AI carrying out connected tasks to draw together student work, rubric results, and reflections to provide an ongoing picture of learning across a program. Faculty could identify a problem, adjust instruction, and examine the next round of evidence while students still have time to benefit. I would test whether that faster feedback actually improves learning. AI may replace some assessment positions as institutions automate analysis and reporting. We should take that possibility seriously. The five roles may outlast the job title, but people must still decide what the evidence means, whose experience is missing, and which changes are warranted.”

About Ruth C. Slotnick

Ruth C. Slotnick, former Director of Assessment at Bridgewater State University

Ruth C. Slotnick, Ph.D., is a higher education and assessment consultant and Associate Editor of Research & Practice in Assessment. She retired as Director of Assessment at Bridgewater State University in September 2026. Her work focuses on institutional assessment, faculty partnership, qualitative inquiry, equity, and generative AI. She co-leads a national Community of Practice on generative AI in assessment with Will Miller and John Hathcoat and serves with them as a co-editor of RPA’s special focus on AI in assessment.

About the authors

  • Ruth C. Slotnick (Office of Assessment, Bridgewater State University, USA, at the time of the study)
  • Joanna Z. Boeing (Office of Assessment, Bridgewater State University, USA, at the time of the study)

Read the article

Read the full research article, first published online in 2024, “Enhancing qualitative research in higher education assessment through generative AI integration: A path toward meaningful insights and a cautionary tale,” published in New Directions for Teaching and Learning in 2025.

Full citation

Slotnick, R. C., & Boeing, J. Z. (2025). Enhancing qualitative research in higher education assessment through generative AI integration: A path toward meaningful insights and a cautionary tale. New Directions for Teaching and Learning, 2025(182), 97–112. doi.org/10.1002/tl.20631

View the publication

We are grateful to Dr. Slotnick for sharing her perspective on this study and for her contribution to the careful, transparent use of AI in assessment and qualitative research.

Research, accuracy and responsible AI

How Evidano's output has been evaluated, how its models were built, how your data is handled, and how to disclose or cite AI use in your own work.

  • Resource

    Human vs AI: validated accuracy benchmarks

    Four head-to-head comparisons against expert human analysis — 371 interview transcripts with Arizona State and Penn State, 298 evaluation reports, 224 open-ended survey responses with UT Austin and Wichita State, and a 160-response manual-coding review.

  • Resource

    How Evidano’s models were trained

    Model provenance for research-ethics review: a provenance-tiered curated corpus, and customer uploads, prompts and outputs excluded from training entirely.

  • Resource

    Data security for qualitative research

    Encryption in transit and at rest, customer-controlled deletion, regional storage, and SOC 2 Type 2, GDPR, HIPAA-ready and CCPA/CPRA compliance.

  • Resource

    How to cite and disclose Evidano

    Citation formats in APA, MLA, Chicago, Harvard and Vancouver, methods-section wording per workflow, and an AI-policy review of 41 journals across 8 disciplines.