Evidano home
Published in JAMIA OpenResponsible AIUniversity of Utah & VA Salt Lake City

What AI-Assisted Thematic Analysis Gains in Speed, and What Human Review Still Protects

Evidano8 min read
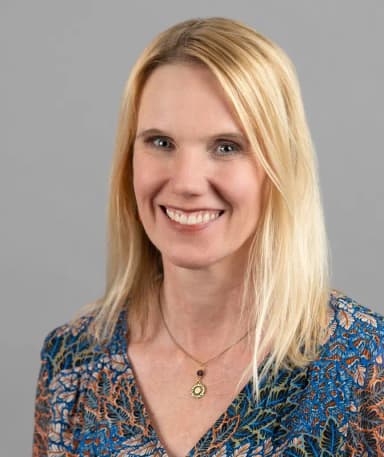
Jorie M. Butler, behavioral scientist at the University of Utah and VA Salt Lake City

Picture a research team with eight interview transcripts, a deadline approaching, and a familiar qualitative-analysis problem: every transcript must be read closely, coded consistently, discussed with colleagues, and then synthesized into themes without flattening the details that make participants’ accounts meaningful. The work is intellectually valuable, but it is also slow. If an AI system can compress that workflow from days of person-time to hours, the real question is not simply whether it is faster. It is what, exactly, might be lost in the compression.

That question sits at the centre of a 2026 JAMIA Open methodological validation study led by Jorie M. Butler and colleagues. The team tested a three-stage large language model workflow for thematic analysis of healthcare interviews, then compared its codes and themes with a human-only reference analysis produced by an experienced four-person coding team. Rather than judging the AI by surface resemblance alone, they examined conceptual similarity, missed content, thematic framing, time, cost, and the places where human review still mattered.

We spoke with Jorie M. Butler, PhD, of the University of Utah and VA Salt Lake City, to learn more about what this comparison reveals about AI-assisted thematic analysis, methodological transparency, and the role of researcher judgement.

About the article

Research question

Can a simple, structured, multi-step LLM workflow produce thematic-analysis codes and themes that are conceptually close to a human-only analysis of healthcare interviews, while reducing the time and cost required? The study also asks whether that efficiency can be achieved without losing traceability and interpretive usefulness.

Key finding

The LLM-assisted workflow aligned closely with the human reference on most codes and themes and reduced recorded analysis time from about 39 person-hours to 5. But the AI produced broader, less granular coding, missed some distinctions, and sometimes framed themes differently, reinforcing the need for researchers to inspect and interpret the output rather than treat similarity scores as a substitute for judgement.

Why this research matters

Qualitative research depends on interpretation. A code is not merely a label attached to text, and a theme is not just a cluster of frequent words. Researchers make decisions about what counts as meaningful, which differences should remain separate, how participants’ language is represented, and whether an apparent pattern fits the wider dataset. The attraction of large language models is obvious: they can process text quickly and generate coherent summaries, codes, and themes. The risk is equally clear: fluency can make an interpretation look settled before a researcher has checked whether it is faithful to the data. Butler reflected on the broader significance of the study: “I do think we are looking at a new world in terms of the need for research efficiency and speed. This is an option to consider, and there will undoubtedly be many more advances over the coming months and years.”

This study matters because it turns that general debate into a concrete workflow comparison. The researchers did not ask whether an LLM could produce something that looked like thematic analysis. They asked how closely a staged AI-assisted process reproduced a human-coded reference standard, where it diverged, and what the practical trade-offs looked like in person-hours and cost. That makes the paper useful not only to biomedical informatics teams, but also to researchers in education, policy, implementation science, organizational research, and other fields where interview datasets can become difficult to analyse at scale.

Key findings from the article

Three findings stand out because they show both the promise and the limits of the approach.

  • The LLM matched most of the human coding at the study’s semantic-similarity threshold. After refinement, the LLM produced 25 codes compared with 50 human-generated codes. Every LLM code matched at least one human code, giving 100% precision under the study’s definition, while 44 of the 50 human codes were matched, giving 88% recall. The unmatched human codes included details about the physicality of the wearable, such as watch size and band issues, along with the “personal value” of patient-generated health data and open-ended questions.
  • Theme-level agreement was high, but agreement did not mean identical interpretation. The three human themes and their closest LLM counterparts had cosine-similarity scores from 0.80 to 0.83. Manual review found broadly consistent thematic boundaries, yet the paper also documents meaningful differences in emphasis and emotional framing. One human theme focused on whether future contribution of patient-generated health data would be feasible for older adults, while the paired LLM theme emphasized technical barriers, unclear communication, motivation, and trust.
  • The time and cost difference was large in this dataset. The human-only analysis took about 39 person-hours and was estimated at $1,923.73 in labour, or about $240 per transcript. The LLM-assisted process took about 5 person-hours and, using the graduate stipend rate plus the subscription cost, was estimated at $236.80 in total, or about $29.60 per transcript. The authors caution, however, that some of the apparent saving could shrink if a researcher using AI still needs substantial time to become deeply familiar with the data for interpretation and reporting.

Taken together, the findings suggest that the strongest case for AI is not that it removes the analyst, but that it can reorganize where human effort is spent. The model handled much of the repetitive structuring quickly, while the most consequential work remained in checking distinctions, context, and framing. Butler reflected on the comparison: “For the most part, our team was surprised by how well this worked (and with today’s newer models it would be even better). In the supplementary materials, you can see all of the code pairings (human and AI). I think that many of the LLM-generated codes were more detailed than the human codes, and helped us to think through our results.”

Methods and research approach

The study used eight deidentified transcripts from interviews with adults aged 65 and older who had contributed patient-generated health data through a mobile application and wearable device. The data included surveys, prompted photographs, and physical-activity and sleep information from a Garmin smartwatch. For the human reference analysis, four experienced coders worked primarily inductively. They reviewed the first three transcripts together, developed and refined a codebook, double-coded the remaining transcripts, adjudicated discrepancies, and then synthesized 50 codes into three themes.

The AI-assisted workflow deliberately broke thematic analysis into three separate stages. First, each transcript was analysed in its own ChatGPT conversation to generate codes, definitions, and supporting quotations. Second, GPT-4o was prompted to merge overlapping codes while preserving a mapping back to the originals. Third, GPT-4.5 grouped the 25 refined codes into themes and then consolidated them to three so they could be compared with the human reference structure. The researchers also checked quoted text against the transcripts. They found no invented quotations, though the model occasionally shortened wording slightly.

For comparison, the team used sentence-t5-xxl embeddings and cosine similarity with a threshold of 0.70. This captures similarity in meaning rather than simple word overlap, but the authors are explicit about its limitations. Shared terms can inflate similarity, short or specialized phrases can be difficult for embedding models, and semantic closeness is not the same as interpretive correctness. The dataset was also relatively straightforward, and the human team already knew the clinical context. Those features limit how confidently the efficiency and performance results can be generalized to more complex qualitative studies.

Broader implications

The paper points toward a hybrid model of qualitative analysis. A staged LLM process can generate and consolidate codes quickly, preserve links to supporting quotations, and provide an initial thematic structure. A researcher can then focus attention where the model is most vulnerable: subtle distinctions, minority perspectives, temporal differences, emotional valence, domain-specific meaning, and the decision about whether two apparently similar ideas should actually remain separate.

For research teams, that shifts the practical question from “Can AI do thematic analysis?” to “Which analytic tasks can be delegated, and what must still be checked by someone who knows the data?” The authors argue that transparency will be essential, including sharing prompts, intermediate outputs, and evaluation criteria where possible. Butler offered practical guidance for teams designing such workflows: “I think this is going to be an important question for some time. At this point, I would say it is easy to see superficial results as better than they are, so I think reviewing the LLM-generated codes in iterations is really key, particularly when there is not a full human-coded set to compare to (as, of course, we want to move to). As we stated in this paper, this was a simple dataset. Now we are testing some more complex data and thinking about workflows and standards for different situations.”

The study does not establish that LLM-assisted thematic analysis is universally equivalent to human analysis, nor that faster output is automatically better analysis. It shows something more useful: under a transparent, structured workflow, an LLM can reproduce much of a human reference analysis on a focused healthcare interview dataset while making some predictable kinds of simplification. Future work will need to test whether that balance holds across harder datasets, different qualitative traditions, more specialized domains, and research questions where nuance is the result rather than a detail around it.

About Jorie M. Butler

Jorie M. Butler, behavioral scientist at the University of Utah and VA Salt Lake City

Jorie M. Butler, PhD, is a behavioral scientist affiliated with the University of Utah Spencer Fox Eccles School of Medicine and VA Salt Lake City Health Care System. Her work focuses on sociotechnical systems, implementation science, patient-centered care, medical decision-making, geriatrics, and the design and evaluation of health information technologies. Her methodological expertise includes qualitative, quantitative, survey, mixed-methods, and usability research. She serves as Associate Director for Education and Evaluation in the VA Salt Lake City Geriatric Research, Education and Clinical Center and is a Principal Investigator in the VA Salt Lake City IDEAS Center of Innovation.

About the authors

  • Jorie M. Butler (Department of Biomedical Informatics, Department of Internal Medicine, University of Utah School of Medicine; VA Salt Lake City, United States)
  • Makoto Jones (VA Salt Lake City IDEAS Center of Innovation; Division of Epidemiology, University of Utah School of Medicine, United States)
  • Christian Balbin (Department of Biomedical Informatics, University of Utah School of Medicine, United States)
  • Peter Taber (Department of Biomedical Informatics, University of Utah School of Medicine, United States)
  • Guilherme Del Fiol (Department of Biomedical Informatics, University of Utah School of Medicine, United States)
  • Rachel Dalrymple (Department of Biomedical Informatics, University of Utah School of Medicine, United States)
  • Kensaku Kawamoto (Department of Biomedical Informatics, University of Utah School of Medicine, United States)

Read the article

Read the full research article, “Sociotechnical analysis of qualitative data using a large language model-assisted framework with performance compared to a human-only coded reference standard,” published in JAMIA Open in 2026.

Full citation

Butler, J. M., Jones, M., Balbin, C., Taber, P., Del Fiol, G., Dalrymple, R., & Kawamoto, K. (2026). Sociotechnical analysis of qualitative data using a large language model-assisted framework with performance compared to a human-only coded reference standard. JAMIA Open, 9(5), ooag091. doi.org/10.1093/jamiaopen/ooag091

View the publication

We are grateful to Dr. Butler for sharing her perspective on this study and for her contribution to the responsible, transparent use of AI in qualitative research.

Research, accuracy and responsible AI

How Evidano's output has been evaluated, how its models were built, how your data is handled, and how to disclose or cite AI use in your own work.

  • Resource

    Human vs AI: validated accuracy benchmarks

    Four head-to-head comparisons against expert human analysis — 371 interview transcripts with Arizona State and Penn State, 298 evaluation reports, 224 open-ended survey responses with UT Austin and Wichita State, and a 160-response manual-coding review.

  • Resource

    How Evidano’s models were trained

    Model provenance for research-ethics review: a provenance-tiered curated corpus, and customer uploads, prompts and outputs excluded from training entirely.

  • Resource

    Data security for qualitative research

    Encryption in transit and at rest, customer-controlled deletion, regional storage, and SOC 2 Type 2, GDPR, HIPAA-ready and CCPA/CPRA compliance.

  • Resource

    How to cite and disclose Evidano

    Citation formats in APA, MLA, Chicago, Harvard and Vancouver, methods-section wording per workflow, and an AI-policy review of 41 journals across 8 disciplines.