Evidano home
gLOCAL Evaluation Week 2026 paperResponsible AIIMACON Consulting Group, Poland

Where AI Can Help an Evaluation, and Where It Should Stop

Evidano10 min read
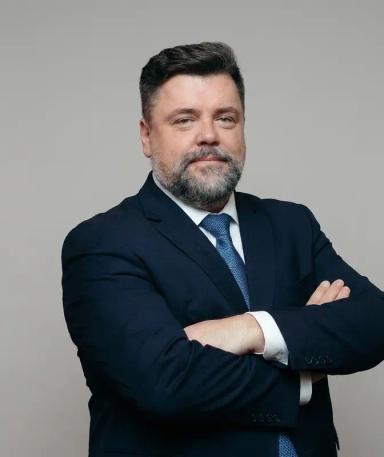
Sergei Gotin, Co-founder and Managing Partner of IMACON Consulting Group

Curator spotlight: this paper is featured independently and does not evaluate Evidano.

Imagine an evaluation team returning from fieldwork with interview recordings, survey data, internal reports, multiple languages, and a deadline already approaching. AI could transcribe the audio, help test a survey, search documents, suggest codes, translate working text, and write analysis scripts. But each shortcut raises a different question: what data is the tool touching, where does that data go, and who remains responsible for the judgement that follows?

That practical problem sits at the centre of Sergei Gotin’s 2026 conference paper, “Navigating Multiple AI Tools Across One Evaluation: A Practitioner’s Four-Level Framework for Responsible AI Integration in Monitoring and Evaluation.” It grew out of his talk at the gLOCAL Evaluation Week 2026 panel “AI and Evaluation: From Practice to Provocation” in Tbilisi. Rather than asking whether an evaluation should “use AI” in the abstract, Gotin argues that evaluators need to separate the workflow into distinct tasks and match each task to an appropriate level of technical and governance control.

We asked Sergei Gotin, Co-founder and Managing Partner of IMACON Consulting Group, how evaluators can use AI without handing over the interpretive responsibilities that make evaluation credible.

About the article

What the paper asks

How can an evaluation team use several AI tools across transcription, anonymisation, coding, document review, quantitative analysis, translation, and reporting while keeping data protection, ethics, contractual obligations, and professional judgement intact? The paper asks for a workable decision framework rather than a single rule for all AI use.

The main argument

Gotin proposes four levels of AI integration based on what a tool is allowed to touch and what governance is required, with the anonymisation step acting as the critical gate between raw personal data and most downstream AI-assisted work. Across all levels, the framework keeps causal interpretation, evaluative judgement, conclusions, and recommendations with human evaluators.

Why this matters

The paper matters because evaluation work rarely resembles a clean laboratory exercise. Teams handle recordings, names, locations, confidential documents, multilingual interviews, survey files, and commissioner rules at the same time. A blanket “AI allowed” or “AI prohibited” policy can therefore hide the real issue: a spell-checker, a local transcription model, a cloud coding system, and a sealed server processing sensitive material do not create the same risks.

Gotin’s framework turns that broad debate into a sequence of operational decisions. It asks evaluators to identify the data path first, then decide what safeguards, approvals, and human checks are appropriate. That shift is especially useful for commissioners and practitioners who need to negotiate responsible use before an evaluation begins. Gotin reflected on the broader significance of the paper: “‘Do you use AI?’ is a question with no useful answer. A spell-checker, a speech-to-text model on an offline laptop and a cloud model coding transcripts are three different decisions with three different risks. Once you break the evaluation into tasks and ask, for each one, what the tool touches and who signs it off, a cautious commissioner usually stops saying ‘no AI’ and starts negotiating a written protocol. In my experience that conversation moves more commissioners than any general appeal to AI ethics.”

Key ideas from the paper

Three contributions are especially useful because they connect governance principles to the ordinary mechanics of evaluation work.

  • Anonymisation is the framework’s central gate, not a routine preprocessing step. Level 2 allows raw personal data to be handled only for the purpose of stripping identifiers, using manual processing or an offline model controlled by the evaluation team. Gotin stresses that what practitioners often call anonymisation is legally still pseudonymisation while the identity key exists, so downstream cloud processing still depends on appropriate contractual safeguards. Only after this gate does the framework open most Level 3 uses, such as coding anonymised transcripts or searching a protected project corpus.
  • Commissioners are not uniformly opposed to AI, but they often need a clearer account of the data path. From roughly 30 evaluation tenders received between 2024 and 2026, Gotin describes about 5% as prohibitive, 45% as cautious, 45% as open to negotiation, and 5% as supportive. He explicitly treats those shares as indicative rather than precise because the sample is small. His operational observation is that some restrictive positions become negotiable when evaluators can distinguish public cloud tools from paid no-training services and offline or isolated models, and can explain those differences before bidding rather than after award.
  • Human verification is built into the workflow, including where AI adds measurable speed or a second analytical pass. The paper reports survey deployment shrinking from days to minutes and automated testing that can replace a full working day with roughly 30 to 60 minutes. In two-tier thematic coding used across IMACON evaluations in 2025–2026, the AI track surfaced codes the human track had missed, an additional 3–6% depending on codebook strictness, and on review human coders accepted roughly half of them. These are practitioner observations rather than controlled benchmarks, but they illustrate the paper’s core design: AI can surface candidates or build tools, while a named evaluator decides what counts.

Taken together, the examples suggest that the most useful distinction is not between “manual” and “AI” evaluation, but between delegated processing and retained judgement. The framework repeatedly gives software bounded jobs while preserving an auditable human decision point. Gotin reflected on the evidence from practice: “Two things surprised me. The first was where the risk actually sat. When we audited every AI tool used on one evaluation, the only tool we had to exclude outright was a popular grammar checker, the one everybody treats as harmless: its no-training guarantee depended on region and licence tier, and we could not confirm it for every account. The tools that feel least risky deserve the closest reading of the terms. The second came after the paper. We have since measured our human + AI coding more rigorously, and the AI track contributes noticeably more than the figures I reported. It is still a second coder rather than a replacement, and every suggestion it makes is adjudicated by a person against the source.”

Where the framework comes from

This is a practitioner framework and conference paper, not a controlled effectiveness study. Gotin develops it from more than two years of hands-on AI integration in evaluations funded by bodies including the EU, USAID, and BMZ across Eastern Europe, the South Caucasus, and Central Asia. Its evidence base includes tender language from roughly 30 evaluation opportunities, operational experience from completed projects, high-risk protocols that have passed independent third-party audit, and examples of seven AI-assisted applications used by IMACON in 2026.

The framework sorts work into four levels. Level 1 covers tasks that touch no substantive project content. Level 2 handles raw personal data only to remove identifiers. Level 3 permits anonymised or pseudonymised content under a written protocol agreed with the commissioner. Level 4 reserves sensitive identified content for sealed infrastructure with the strongest governance, requiring a full data-protection impact assessment. Alongside this, five standing principles cover keeping sensitive data away from any third-party model, local-first infrastructure, paid services with training disabled when cloud tools are used, AI-written scripts rather than AI judgements, and human validation of every output that could influence an evaluation.

The paper is deliberately candid about its limits. The tender proportions are approximate, several efficiency and coding figures come from one consultancy’s practice, and the framework has not been tested as a universal standard across sectors or jurisdictions. Gotin also discloses that IMACON’s own AI-integration services and tools are discussed in the paper, and that AI tools were used for transcription, drafting assistance, and language refinement during preparation. These disclosures make the paper best read as a transparent, experience-based framework that invites further testing rather than as definitive validation.

Broader implications

For evaluators, the immediate implication is procedural: map the workflow before selecting the tool. A project may legitimately use AI for an interview guide, local transcription, code suggestions, document retrieval, or statistical scripting under different controls, while still prohibiting AI from deciding what the evidence means. That is more demanding than adopting a single approved-tool list, but it is also more adaptable when models, vendors, contracts, and commissioner requirements change.

For commissioners, research managers, and methods trainers, the paper offers a vocabulary for asking better questions. Instead of “Did you use AI?”, a review can ask what content each system touched, whether identifiers were present, where processing occurred, what contractual protections applied, and who verified the output. The framework also leaves commissioners a genuine choice: in IMACON’s practice, a commissioner who prefers a fully AI-free evaluation can have one at no change in price or timeline, because the core analysis is manual by design. The unresolved questions are substantial: how well the four levels travel beyond international development evaluation, how different legal regimes alter the boundary between levels, and which quality-control procedures should be independently validated.

The paper also treats responsible AI as a question of infrastructure and capacity, not only of policy. Drawing on IMACON’s practice, Gotin estimates that a well-designed AI deployment can cut the cost and effort of data processing on medium and large evaluations by up to half, mainly through software built for the specific evaluation and amortised over large data volumes. Sealed infrastructure, by contrast, is costly, and the paper reserves it for large studies, such as programme evaluations with more than 200 interviews and focus groups across five to seven countries. The same economics shape the paper’s practical recommendation: few evaluation teams will find it efficient to build secure infrastructure, protocols and tools from scratch for a single assignment, so a consortium in which one partner carries the AI component and the secure handling of data is often the more workable route, with data-protection responsibility formalised under a data-processing agreement.

The paper’s strongest boundary is also its clearest statement about professional responsibility: theory of change, causal interpretation in context, and the final evaluative judgement remain human work. That position leaves room for extensive automation without pretending that judgement itself is merely another processing task. Looking ahead, Gotin reflected on what practitioners should do next: “Be most cautious about the step everyone treats as routine: anonymisation. Replacing names with codes is pseudonymisation, not anonymisation, and in a small context a town or a media outlet can identify a person as surely as a name. As for standards, I would like the profession to stop trading prompts and start standardising quality control: independent AI passes that cross-check coding, translation and statistics, so that a disagreement between two models triggers human review the same way a disagreement between two coders does. That is triangulation, applied to a new kind of analyst. Few teams will build that machinery for a single assignment, and they shouldn’t have to. On large studies I expect the AI component to be carried more and more by a specialist partner in the consortium, under a protocol the commissioner can audit.”

About Sergei Gotin

Sergei Gotin, Co-founder and Managing Partner of IMACON Consulting Group

Sergei Gotin is Co-founder and Managing Partner of IMACON Consulting Group (Poland). He has more than 25 years of international experience and has led 60+ external evaluations for UN agencies (UNDP, UNICEF, UNFPA, UNIDO) and the UN Office of Internal Oversight Services, the European Union, USAID, BMZ, Sida and other donors. His practice combines theory-based and mixed-method evaluation, organisational capacity assessment, and capacity-building in the Logical Framework Approach and Results-Based Management. A physicist by training and former software development team leader, he leads IMACON’s work on the responsible integration of AI into evaluation, including secure AI-assisted processing of large qualitative datasets for evaluation and research consortia. He is a member of the Polish Evaluation Society.

LinkedIn · imacon.org

About the authors

  • Sergei Gotin (IMACON Consulting Group, Poland)

Read the article

Read the full conference paper, presented at gLOCAL Evaluation Week 2026 (Tbilisi, Georgia, 3 June 2026), “Navigating Multiple AI Tools Across One Evaluation: A Practitioner’s Four-Level Framework for Responsible AI Integration in Monitoring and Evaluation,” published on Zenodo in 2026.

Full citation

Gotin, S. (2026, June 3). Navigating multiple AI tools across one evaluation: A practitioner’s four-level framework for responsible AI integration in monitoring and evaluation [Conference paper]. gLOCAL Evaluation Week 2026, Tbilisi, Georgia. Zenodo. doi.org/10.5281/zenodo.21535629 · Russian translation: doi.org/10.5281/zenodo.21535825 · Polish translation: doi.org/10.5281/zenodo.21535863

View the publication

We are grateful to Sergei Gotin for sharing his perspective on this paper and for his contribution to the responsible, transparent use of AI in evaluation.

Research, accuracy and responsible AI

How Evidano's output has been evaluated, how its models were built, how your data is handled, and how to disclose or cite AI use in your own work.

  • Resource

    Human vs AI: validated accuracy benchmarks

    Four head-to-head comparisons against expert human analysis — 371 interview transcripts with Arizona State and Penn State, 298 evaluation reports, 224 open-ended survey responses with UT Austin and Wichita State, and a 160-response manual-coding review.

  • Resource

    How Evidano’s models were trained

    Model provenance for research-ethics review: a provenance-tiered curated corpus, and customer uploads, prompts and outputs excluded from training entirely.

  • Resource

    Data security for qualitative research

    Encryption in transit and at rest, customer-controlled deletion, regional storage, and SOC 2 Type 2, GDPR, HIPAA-ready and CCPA/CPRA compliance.

  • Resource

    How to cite and disclose Evidano

    Citation formats in APA, MLA, Chicago, Harvard and Vancouver, methods-section wording per workflow, and an AI-policy review of 41 journals across 8 disciplines.