Evidano home
Published in Anatomical Sciences EducationResponsible AIMonash University

What Makes AI-Supported Qualitative Analysis Trustworthy?

Evidano8 min read
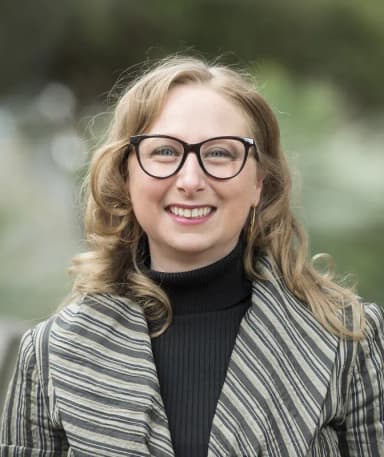
Michelle D. Lazarus, Professor at Monash University

Imagine a health-professions researcher facing hundreds of reflective diaries. Some entries are descriptive, others deeply reflective, and many depend on context that is easy to lose at scale. AI can scan the collection quickly, but when it labels a passage as emotional, can it tell whether the student felt that emotion or was describing someone else who did?

That tension sits at the centre of “Risky or rigorous? Developing trustworthiness criteria for AI-supported qualitative data analysis,” a viewpoint in Anatomical Sciences Education led by qualitative researchers Michelle D. Lazarus and Georgina C. Stephens with learning-analytics colleagues. Instead of asking whether AI belongs in qualitative research, the authors ask what must change so AI-supported analysis can still be credible, dependable, reflexive, transferable, and confirmable.

We spoke with Michelle D. Lazarus, Professor at Monash University and Director of the Centre for Human Anatomy Education, to learn more about what rigorous, human-led collaboration with AI should look like in qualitative data analysis.

About the article

What the article asks

How can researchers use AI to support qualitative data analysis without weakening the standards of rigor, or trustworthiness, expected in interpretivist qualitative research? More specifically, which established trustworthiness criteria need to be reconsidered when an AI system becomes part of the analytic process?

The main argument

The authors argue that AI can support rigorous qualitative analysis only when its role is bounded, transparent, and critically examined within the study design by the humans leading the project. They adapt five familiar criteria (credibility, dependability, reflexivity, transferability, and confirmability) into practical questions about tool selection, training data, human oversight, documentation, contextual judgement, and traceability to source data.

Why this matters

AI can help researchers process large collections of interviews, diaries, documents, and open-ended responses, apply a framework consistently, and notice patterns that are hard to compare manually. The risk is treating speed or consistency as evidence of methodological quality.

Lazarus and her co-authors make the case that rigor cannot be outsourced to software. The more researchers move from generating interpretations themselves to evaluating machine-generated outputs, the more important it becomes to document what the AI was designed to do, what it was trained on, what it cannot understand, and how researchers challenged its suggestions. Asked what she sees as the most important change for researchers and others who evaluate and use AI-supported qualitative research, Lazarus replied: “Thinking that we need to do things differently because of AI. To be able to make the best choices of the when, which and how of AI-supported qualitative analysis, we need to be as aware and knowledgeable about the qualitative methodologies as we were prior to AI, arguably even more.” Their framework therefore matters not only to researchers using AI, but also to supervisors, journal reviewers, editors, and institutions deciding what transparent AI-assisted qualitative work should look like.

The article avoids a simple pro-AI or anti-AI position. Its point is methodological: a tool may strengthen one part of a study while weakening another. Pattern recognition at scale can be useful, yet still miss the contextual meaning on which interpretivist research depends.

Key ideas from the article

Three contributions stand out because they turn an abstract debate about AI ethics into concrete choices that qualitative researchers can inspect and report.

  • Rigor depends on fit between the research question, worldview, and AI tool. The case used a purpose-built reflexive expressions parser on 230 diary entries from 41 medical students who reflected on certainty and uncertainty at six points during 2020. Developed from 13,841 student reflections, the parser identified theoretically defined patterns of reflexive language rather than a topic. The authors argue that credibility and dependability require researchers to understand why a system fits the question, how it was trained, and where its limits lie, and whether those limits are acceptable for the given research question or aims.
  • Human review changed the meaning of an AI-generated pattern. The parser grouped entries containing strong emotional language, but researchers found that some emotions were being observed in others rather than experienced by the students themselves. One participant, for example, described other students as “scared” to speak. The software detected emotion, grouping the diary alongside other reflections with emotions; human interpretation established whose emotion it was and why that distinction mattered.
  • Trustworthiness can be translated into specific AI-era reporting practices. The article maps five established criteria onto AI-supported analysis. Suggested practices include audit trails separating AI-led from researcher-led steps, disclosure of training and intended purpose, reflexive accounts of how AI influenced judgement, attention to training context and transferability, and examples of coded outputs linking analysis back to primary data. The authors call for a “human-leading-the-loop” approach in which interpretive responsibility begins with and stays with the researchers.

Taken together, the paper suggests that the most revealing moments may be the points where AI and researcher judgement diverge. Those disagreements expose what the system can see, what it cannot see, and what the research question actually requires. Lazarus reflected on that experience: “Indeed, the confusion I felt reviewing the AI categories was a really good reminder of why the human really matters in qualitative research. What AI can do is identify patterns in the data I didn’t see, but not all of those patterns are useful or valuable. The AI-supported research, instead of making me fearful that I would be replaced, solidified my human role in the process.”

Where the framework comes from

This is a methodological viewpoint rather than a validation study of AI accuracy. The authors combine literature on qualitative rigor with lessons from an ongoing secondary analysis of medical-student diaries. The larger project was interpretivist, treating knowledge as socially constructed and open to multiple perspectives, and the paper focuses on “Big Q” qualitative research, where researcher subjectivity is part of interpretation.

The parser coded all 230 diary entries, after which epistemic network analysis examined co-occurring reflexive-expression categories and clustered diaries by pattern. Lazarus and Georgina C. Stephens then manually reviewed 15 randomly selected diaries from each cluster using deductive thematic analysis. Three patterns emerged: superficially, partially, and deeply reflective. Cluster patterns remained broadly static over time, while uncertainty-focused reflections contained more expressive codes across all three clusters.

The case also shows clear limits. The parser lacked contextual understanding, substantial researcher time was still required, and no automatic endpoint told the team when analysis was complete. It was also a purpose-built, explainable parser rather than a general commercial LLM. The authors explicitly warn that less transparent proprietary systems create additional dependability problems, so the case does not establish that all AI tools are equally suitable.

Broader implications

For researchers, the paper reframes AI adoption as a methodological decision. Tool choice becomes part of study design: what (and how) does the model “know,” how does that knowledge relate to participants and theory, which decisions remain human, and what evidence lets readers follow the path from raw data to interpretation?

For reviewers and editors, the framework provides a vocabulary for evaluating rigor without requiring AI-assisted work to mimic manual coding. A trustworthy report might document prompts or workflow decisions, describe training and limitations, show samples of machine-coded output, and explain where researchers rejected or refined the system’s interpretation. The case demonstrates why such scrutiny is needed. How these practices translate to rapidly changing general-purpose AI systems remains uncertain.

The broader lesson is that efficiency should not become the main standard by which AI-assisted research is judged. In qualitative work, the goal is not only to process text but to make defensible interpretations about human meaning. Lazarus offered this advice: “When considering an AI tool, you need to be as aware of the qualitative method you are using (and its alignment with the research question/aim) as you are of the technology you are engaging. Given the numerous human check-points required when AI is integrated into the process, thinking that you are going to save time or short-cut your way out of learning qualitative methodology is probably one of the most common mistakes I see.” The paper’s strongest contribution is to make that responsibility visible: AI may extend the researcher’s analytic reach, but it does not inherit the researcher’s accountability.

About Michelle D. Lazarus

Michelle D. Lazarus, Professor at Monash University

Professor Michelle D. Lazarus is the Director of the Monash Centre for Human Anatomy Education within Anatomy & Developmental Biology at the Biomedical Discovery Institute, and Deputy Director of the Monash Centre for Scholarship in Health Education in the Faculty of Medicine, Nursing and Health Sciences at Monash University. She served as a guest editor of Anatomical Sciences Education from 2023 to 2026 and is currently an associate editor for Medical Education. She is internationally recognized for her work on advancing high-quality, evidence-informed education across diverse learning environments, with her research program, centred on exploring adaptive responses to uncertainty, attracting thousands of citations and informing major policy and guideline developments, including national government recommendations. She is also the author of several books, including The Uncertainty Effect: How to Survive and Thrive through the Unexpected and The AI (R)evolution: Valuing Country, Culture and Community in a World of Algorithms. In recognition of her impact, Professor Lazarus has received numerous national and international awards for excellence in teaching, science communication, innovation, and medical education research, including the prestigious Australian Awards for University Teaching. More than a scholar of uncertainty, she embodies it, building a career defined by curiosity, adaptability, and the courage to explore the unknown.

About the authors

  • Michelle D. Lazarus (Centre for Human Anatomy Education and Monash Centre for Scholarship in Health Education, Monash University, Australia)
  • Linxuan Zhao (Centre for Learning Analytics at Monash, Faculty of Information Technology, Monash University, Australia)
  • Andrew Gibson (QUT Centre for Data Science and School of Information Systems, Queensland University of Technology, Australia)
  • Roberto Martinez-Maldonado (Centre for Learning Analytics at Monash, Faculty of Information Technology, Monash University, Australia)
  • Georgina C. Stephens (Centre for Human Anatomy Education, Monash University, Australia)

Read the article

Read the full research article, “Risky or rigorous? Developing trustworthiness criteria for AI-supported qualitative data analysis,” published in Anatomical Sciences Education in 2026.

Full citation

Lazarus, M. D., Zhao, L., Gibson, A., Martinez-Maldonado, R., & Stephens, G. C. (2026). Risky or rigorous? Developing trustworthiness criteria for AI-supported qualitative data analysis. Anatomical Sciences Education, 19(2), 330–337. doi.org/10.1002/ase.70125

View the publication

We are grateful to Professor Lazarus for sharing her perspective on this article and for her contribution to rigorous, transparent use of AI in qualitative research.

Research, accuracy and responsible AI

How Evidano's output has been evaluated, how its models were built, how your data is handled, and how to disclose or cite AI use in your own work.

  • Resource

    Human vs AI: validated accuracy benchmarks

    Four head-to-head comparisons against expert human analysis — 371 interview transcripts with Arizona State and Penn State, 298 evaluation reports, 224 open-ended survey responses with UT Austin and Wichita State, and a 160-response manual-coding review.

  • Resource

    How Evidano’s models were trained

    Model provenance for research-ethics review: a provenance-tiered curated corpus, and customer uploads, prompts and outputs excluded from training entirely.

  • Resource

    Data security for qualitative research

    Encryption in transit and at rest, customer-controlled deletion, regional storage, and SOC 2 Type 2, GDPR, HIPAA-ready and CCPA/CPRA compliance.

  • Resource

    How to cite and disclose Evidano

    Citation formats in APA, MLA, Chicago, Harvard and Vancouver, methods-section wording per workflow, and an AI-policy review of 41 journals across 8 disciplines.